A practical guide to learning bioinformatics, finding a research direction, and building your first scientific project in the age of AI.
Originally published: August 31, 2020
Guide updated: November 2026
Resources reviewed: November 12, 2026
Bioinformatics has changed considerably since we first published this guide in 2020. Artificial intelligence, freely available learning materials, and increasingly capable scientific software have opened up new ways to learn, experiment, and contribute to research.
We’ve updated this guide to reflect those changes, while keeping the original goal: helping you find your way into bioinformatics without feeling overwhelmed by the size and complexity of the field.
This article is written primarily from the perspective of a software engineer who became interested in biology. But it is intended for anyone interested in bioinformatics, whether you come from biology, laboratory research, computer science, or have little experience in either field.
We will focus on free resources, practical learning, and building something useful. We will also explore how AI assistants can help us learn faster and automate many research tasks, and why understanding the fundamentals matters more than ever.
In This Article
We will explore:
- How to find a direction in bioinformatics that genuinely interests us.
- What AI has changed about learning programming and conducting scientific research.
- Which fundamentals we should learn, and why they still matter.
- How to choose a practical biological problem and begin investigating it.
- A step-by-step learning path using free courses, exercises, and AI tools.
- How to turn our new skills into reproducible projects and a portfolio of work.
Part 1: Why Do You Want to Become a Bioinformatician?
Let’s start with a question: What made you interested in bioinformatics?
If you know the answer, it becomes much easier to decide what to learn next. You have a reason to explore a subject, understand a particular tool, or spend time working through a difficult problem.
But there are many of us who don’t have a clear answer yet. Perhaps you enjoy programming and want to do something connected to science. Maybe you have a background in biology and want to analyse your experimental data. Or perhaps you came across an interesting biological discovery and wondered whether you could investigate something similar yourself.
All of those are perfectly good reasons to begin.
The difficulty is that bioinformatics is an enormous field. It combines biology, computer science, mathematics, statistics, and many other subjects. Ask someone what you need to learn to become a bioinformatician, and you might receive a list of programming languages, databases, scientific software, books, and university courses.
That information might be correct, but it isn’t always helpful when you are just getting started.
Start With a Problem, Not a Collection of Tools
Imagine spending months learning how to use a hammer, a saw, a drill, and various other tools. You become reasonably good at using them, but eventually you ask yourself: what am I supposed to build?
Now imagine approaching the problem from a different direction.
You decide that you want to build a small house. You can research what materials and tools you need, understand the basic construction process, and begin learning the necessary skills one at a time.
You now have a reason to learn how to use each tool.
Think back to primary or secondary school. We might have memorized a date in history, a formula in maths or physics, or a rule in chemistry just long enough to pass an exam. We could give the right answer on the day and forget it a week later. When we didn’t understand what the formula could help us work out or why the historical event mattered, it was hard to see a reason to remember it.
Learning bioinformatics can feel the same if our plan is to collect skills and hope they lead to a good job. Wanting a good job is a perfectly reasonable motivation. A small project gives us something closer to work towards. When a new idea helps us answer a question we care about, we have a reason to learn it and a way to see our progress.
For example, suppose you want to join two DNA reads. A read is a short stretch of DNA letters that a sequencing machine has read. Imagine our two reads are ATGC and TGCA. The first ends in TGC, and the second begins with those same three letters. Line them up at TGC, and you get one possible join, ATGCA.
Let’s ask Python the same question. A string is a piece of text, like "ATGC". The square brackets tell Python which letters to take. [-3:] takes the last three letters, and [:3] takes the first three.
# These are our two short DNA reads.
left = "ATGC"
right = "TGCA"

# Is the end of the first read the same as the start of the second?
match = left[-3:] == right[:3]
print(match)  # True: both sets of three letters are TGC.

# Keep the first read and add the letter after the overlap.
print(left + right[3:])  # ATGCA
True means the two ends match. Since they match, we can keep the first read and add just the last A from the second. That gives us one possible join, ATGCA.
Look what we just did. We took two pieces of DNA and worked out how they could fit together. Imagine doing that with millions of pieces, some with mistakes and some that look almost the same. That’s the challenge of genome assembly. People do it all the time, and there’s still room for better ways to put bigger genomes together in less time. We started with just two pieces and a few lines of Python.
Joining many reads to reconstruct a longer stretch of DNA is called genome assembly. In Part 4, we’ll come back to these same two reads and see what happens when a third read could fit in the same place.
Imagine you walk past a flower in the afternoon and barely notice it. You walk past it again after dark, and this time it smells sweet. What changed? Let’s pretend we have a small piece of its DNA. We could pick six letters and count them, but what if we let Python tell us which six-letter pattern shows up most often?
Imagine a little window that shows six letters at a time. We write down the letters we see, move one place to the right, and look again. Python’s Counter is our tally sheet. The loop keeps moving the window until there are fewer than six letters left.
from collections import Counter

flower_dna = "ATTACGCTGAACCATCGCTGAATGTTAGCTGAACAGCAGCTGAAGTATT"
counts = Counter()

# Take six letters at a time, starting one letter farther along each time.
for start in range(len(flower_dna) - 5):
    pattern = flower_dna[start:start + 6]
    counts[pattern] += 1

# Show the pattern with the highest count.
print(counts.most_common(1))  # [('GCTGAA', 4)]
Python found GCTGAA four times. We can check that ourselves. Look for the four bold groups.
Now imagine looking up that whole stretch in a DNA database. In our made-up database, it matches part of a gene in a related flower. That gene carries instructions for making a protein that helps produce a sweet-smelling chemical. Could our flower use a similar gene to make its scent? Could it use that gene more after dark? The database match gives us somewhere to look. To answer those questions, we’d need to check the gene and see what the flower does during the day and at night.
Isn’t that amazing? We started with a flower we could smell on an evening walk, and a few lines of Python gave us something to look for in its DNA. That’s a first taste of how people search for genes and learn about the proteins they make. There’s still room for better tools to find those genes and better ways to check what they do. You can start learning how that works with a question as simple as “Which letters show up most often?”
The DNA and the database entry are made up for this story. You can run the Python and check the count yourself. In Part 4, we’ll take the next step and look at where patterns occur.
Keeping up with bioinformatics is a challenge even when you already know the basics. New libraries and algorithms appear all the time. Familiar tools change, and researchers find new ways to tackle old problems. By the time you work through a long list of tools, some of them may have changed and others may have little to do with the work you want to do. That makes a list of software a hard place to start, even if your goal is to get a job.
Start with a question you genuinely want to answer. Give yourself a clear goal you can work towards, such as comparing a few DNA reads and explaining which ones overlap. That goal helps you decide what to learn this week and what can wait. When the first attempt gets frustrating, being curious about the answer gives you a reason to come back to it.
You can use the same question to keep up as the field changes. Ask an AI assistant to look for recent papers, library updates, or new methods that could help with your specific problem. Ask for links to the original paper or documentation, then check whether the change matters for your data and what you’re trying to find out. For the two reads we just lined up, a few lines of Python are enough to check the overlap. If your project grows to thousands of reads, you might look for a genome assembler, a program that works out how those reads fit together.
You do not need to invent a new scientific method or discover something that nobody has discovered before. Reproducing a small part of an existing study, understanding a biological dataset, or building a simple version of a published algorithm can be an excellent first project.
Your direction does not need to be permanent, either. As we learn more, we will probably discover new interests and change our plans. That is a normal part of learning.
What Kind of Problems Could We Investigate?
Here are a few examples.
Genome assembly: How do scientists reconstruct an organism’s genome when sequencing machines produce many smaller fragments of DNA?
Finding patterns in DNA: Can we identify repeated sequences or interesting regions in a genome, and what might those patterns tell us?
Gene expression: Why are some genes more active in certain cells or under different biological conditions?
Protein research: How does the three-dimensional structure of a protein help scientists understand what it does?
Experimental biology: Can we reproduce the data analysis from a published study and check whether we obtain similar results?
Each of these questions also gives us a way to contribute. If you later try an assembler on real data and it joins two pieces incorrectly, you could share the reads and the steps that produced the join. That gives the people who maintain the tool a way to check what happened. In a gene-expression project, we might reproduce one published chart and document the data, settings, and steps so another learner or researcher can check it. A small pattern-counting project could contribute a clearly explained function and tests that catch mistakes with overlapping matches. A useful contribution can be as simple as making a result easier to repeat or an error easier to find.
We will return to them later and discuss what you might need to study to begin working on each one.
Part 2: Bioinformatics in the Age of AI
One of the biggest changes since the original version of this article is the arrival of increasingly capable AI assistants.
It can feel daunting to watch AI get better at skills we’re still learning. Think about what it used to take to learn something new on your own. We’d track down a book, only to discover that the software it covered had already changed. If the examples didn’t work, we’d search for the right forum, read through old threads, and sometimes wait days for someone to answer.
Now a web-enabled AI assistant can be the place we start. Tell it what you want to understand and how much you already know. It can find a free video or a public course, look through current documentation and forum discussions, and bring the useful parts together in a clear explanation. Ask it to cross-check the important claims against the original sources and give you links so you can see what the explanation is based on.
There’s never been a better time to start learning a complex topic. Imagine putting on your headphones for a walk in the forest and starting a voice chat with ChatGPT, Gemini, or whichever AI assistant you like. You could talk through what worries you about your career or which direction to explore. Tell it what you enjoy and what you already know, brainstorm a few projects, and pick one small enough to try. By the time you get home, you might have a question worth investigating, a short list of what to learn, and a first step you can take that day.
You can pick up that same idea on your phone or computer and ask for something you can see and work through. Ask it to visualize how a Python program scans a DNA string, one position at a time, or draw a labeled diagram of how short sequencing reads fit together. Some AI apps can turn explanations into interactive visuals. Imagine moving the window yourself, predicting which letters come next, and then checking your prediction with a few lines of Python. A question you asked out loud on a walk can become an example you can explore that afternoon.
Give yourself a weekend and a small question. You can learn enough Python to read a DNA sequence, test a simple idea, and write up what you found. That’s a first portfolio project and something concrete to build on. An AI assistant can explain a confusing step or suggest an exercise while you work through the real data yourself.
One Interest Can Lead to Many Research Questions
If you’re wondering what there is to work on in bioinformatics, look at the questions people are still trying to answer.
- Why do some cancers stop responding to treatment?
- How can we measure whether a vaccine response lasts?
- What changes in our cells as we age?
- How do some animals regrow tissue after an injury?
Each question leaves room for people who can make sense of data, check existing results, or build tools others can use.
Regeneration is one area we’re particularly curious about. Think of it as a tree. One branch is bioelectricity. Charged particles such as potassium move through channels in cell membranes, and that movement helps shape the voltage across the membrane. Now a question about regrowing tissue leads into chemistry and physics. In flatworms, researchers have tested how early electrical signals influence whether a head or a tail regrows. On the computational side, we could simulate how changing the flow of ions affects voltage in a group of connected cells.
You can explore these ideas in two studies.
Another branch asks what the cells are doing while a tissue regrows. We could use clustering to group cells with similar gene activity, then compare those groups at different times after injury. A first project could be as focused as recreating one plot from a public flatworm dataset and explaining what it shows. Planarian regeneration dataset and study
You can explore a few branches and spend more time on the one that keeps you asking questions. Ask an AI assistant to unpack a paper, help you find a public dataset, or break one analysis into steps. Then run it yourself and share the data source, code, plot, and what you could verify. That gives a potential employer, lab, or research team something concrete to look at and a way to see how you think.
Not long ago, a researcher who wanted to compare twenty genomes might have needed to find the appropriate databases, download the sequences, prepare the data, install several software tools, write scripts to connect them, and manually inspect the results.
The work could involve days of preparation before reaching the biological question that motivated the experiment.
Today, AI assistants can help with many of these steps.
We can ask an assistant to find appropriate public genome datasets, explain the available analysis methods, write code, prepare a workflow, and help interpret the resulting data. More advanced AI agents can use connected software tools to perform several tasks in sequence.
An AI agent is an assistant that can take actions using tools rather than simply responding with text. Depending on its configuration, it might search databases, run programs, inspect files, and use the results of one operation to decide what to do next.
That means some computational research tasks can become much more automated.
In specialized research facilities, automated laboratory equipment can also perform certain experiments under software control. Some research systems combine computational analysis, experimental measurements, and automated decision-making into repeated cycles.
This is exciting, but it does not mean that an AI assistant can reliably conduct every scientific investigation from beginning to end. Choosing an appropriate research question, evaluating the evidence, recognizing mistakes, and deciding what additional experiments are needed still require careful scientific judgment.
Does This Mean We No Longer Need to Learn Programming?
You might be wondering: if AI can already write code and perform analyses, why should we spend months learning Python, algorithms, or software engineering?
That is a reasonable question.
For some tasks, we may no longer need to write every line of code ourselves. If we need a small script to rename files or create a simple chart, asking an AI assistant to generate it can save a considerable amount of time.
But there is an important difference between getting a program that appears to work and understanding whether it is doing the correct thing.
The better we understand programming and the underlying science, the better we can explain what we want, assess the proposed solution, and recognize when something is wrong.
Knowing more about a subject also changes how we interact with an AI assistant. We can ask more specific questions, provide useful constraints, and understand the consequences of different technical decisions.
If an agent asks whether a DNA search should examine both strands, whether overlapping matches should be counted, or which sequence version should be used, we should understand why those questions matter.
And when an AI assistant gives us a result, we should know how to check it.
This is why learning the fundamentals is still worth our time.
Part 3: Master the Fundamentals of Programming and Scientific Research
For programming, we will focus on Python.
Python remains an excellent general-purpose language because it is relatively easy to read, has a large community, and provides many libraries for scientific work. It is commonly used for working with biological data, statistics, automation, and software development.
You certainly don’t have to use Python for everything. Other languages have important roles in bioinformatics. But Python is a practical place for most beginners to start.
What Do We Mean by Programming Fundamentals?
Fortunately, the initial list is not particularly long.
Start with these concepts, in roughly this order:
- Variables and data types: Learn how to store numbers, text, and other values. In Python, that includes integers, floating-point numbers, strings, and Boolean values. Examples:
int,float,str,bool. - Logic and branching: Learn how to make decisions using
if,elif, andelse, together with comparisons and logical operators. - Loops: Learn how to repeat operations using
forandwhile. We use loops constantly when processing DNA sequences and other biological data. - Functions: Learn how to divide a problem into smaller pieces, pass information into a function, and return a result. Keywords:
def,return. - Data structures: Learn how to use lists, dictionaries, sets, and other collections to organize and process information. Examples:
list,dict,set.
Understanding just some of these concepts will already allow you to write small programs that process DNA sequences.
For example, we could represent a short DNA sequence as a Python string, examine its individual letters, count how often a certain pattern appears, and store those counts in a dictionary.
Once those operations make sense, we can begin working with longer sequences and more interesting algorithms.
We should also learn how to read error messages, debug our programs, and check whether they produce the expected results.
This is similar to learning how to drive a car. Once we understand the fundamental rules and controls, we can apply them in places we have never visited before.
Scientific Software Requires a Few Additional Skills
As our projects become more serious, we will encounter several important concepts beyond basic Python syntax.
They may sound complicated at first, but the underlying ideas are quite simple.
Reproducibility: Another person should be able to repeat our analysis using the same data, methods, and settings, and obtain the expected results.
Provenance: We record where our data came from, which version we used, how it was processed, and which program produced the result.
Pipelines: We connect several operations into one workflow. For example, load a DNA sequence, validate it, count patterns, and save the results.
Testing: We give our software small examples where we already know the correct answer, then check whether the program behaves as expected.
Software structure: We organize our code so individual functions and algorithms can be reused, understood, and maintained instead of writing everything inside one enormous script.
A first counting function may only need ordinary Python. Once we want someone else to run and check a small project, this is the starter toolkit we recommend:
- Python fundamentals. Use strings, loops and functions to process sequences, and lists and dictionaries to organize inputs and counts.
- uv. Manage the project and its dependencies. Keep the lockfile so others can install the same versions of the libraries.
- Pydantic. Validate structured inputs and settings, such as a sequence record with a required identifier, as the project grows.
- pytest. Test small examples with known answers, along with invalid inputs and boundary cases.
Together with the data source and analysis settings, these practices make it easier to repeat a calculation and check that the code does what we intended. We can learn them in that order as the project needs them.
Fortunately, there is an enormous amount of free educational content covering these subjects, including practical Python tutorials and scientific software development lessons on YouTube.
Knowing What to Ask AI Makes a Big Difference
Consider the following request to an AI assistant:
Write a Python algorithm that finds and scores interesting motifs in DNA.
A motif is a DNA, RNA, or protein sequence pattern that may be biologically meaningful.
Modern AI models can certainly produce code in response to this request. They may even generate something that appears impressive.
But what exactly is an interesting motif? How should we score it? Which DNA sequences are we analysing? Should we examine both strands? How do we check whether the results are correct?
The request leaves many important decisions open.
Now consider a more informed request:
We want to create a reusable Python package for analysing DNA sequences.
Use uv to manage the Python project and its dependencies. Organize the code into small, reusable modules, and use Pydantic models where structured input validation genuinely helps.
Create a FASTA loader that reads biological sequence files and preserves their identifiers. Add an algorithm for counting overlapping DNA patterns and a separate, clearly defined method for scoring candidate motifs.
Before implementing the scoring method, help us choose and document its biological assumptions and exact mathematical rules.
Add automated tests using pytest, including small sequences with known answers, invalid inputs, and boundary cases.
Record the input sequence version, analysis parameters, software version, and results so another researcher can reproduce the computation.
Explain the architecture and ask questions wherever the scientific requirements are unclear.
We tried this prompt with Google Antigravity using Gemini 3.8 Flash. The last line asked the agent to raise questions wherever the scientific requirements were unclear. It came back with two decisions for us to make.
Gemini follow-up 1 of 2 · Choose how to score a match
Which candidate motif scoring method would you like us to implement?
- Recommended by the agent: Biophysical log-odds position weight matrix (PWM) based on Berg–von Hippel additive free energy, with pseudocounts and genomic background.
- Information content and relative entropy (Schneider), calculating bit conservation per column and Kullback–Leibler divergence.
- Statistical enrichment using a Z-score and binomial p-value against a random Bernoulli background.
- Consensus distance and mismatch penalty using weighted Hamming distance with transition and transversion penalties.
- Write in a different answer.
Gemini follow-up 2 of 2 · Choose the DNA background
How should null background nucleotide frequencies be defined for scoring?
- Recommended by the agent: A configurable background, uniform by default at 0.25 per base, with options to derive it from target GC content or supply custom frequencies.
- A strictly uniform background fixed at 0.25 per base.
- A background estimated from the input sequence during analysis.
- Write in a different answer.
The first question asks what should count as a good match. A position weight matrix can give different letters different scores at each position. A mismatch method instead measures how far a sequence is from a reference pattern. An enrichment test asks whether a pattern occurs more often than expected, and a measure of information content helps describe how strongly certain positions favour particular letters. These methods answer different questions. The best choice depends on what we want to learn and what data we have.
The second question asks what we should expect before we look for a pattern. Should A, C, G and T all be equally common? Should we estimate their frequencies from the sequence, or use frequencies we supply? If a sequence already contains a lot of G and C, a G- and C-rich pattern can look less surprising when we account for that background. That choice can change the scores even when the DNA stays the same.
We answered the two questions before the agent built the package. The expandable response below is what it reported for that run, including its test results. Your assistant might ask different questions or produce a different design.
Read the full Gemini 3.8 Flash response
The reusable Python package dna-analyzer has been implemented, validated, and tested using uv and Pydantic.

  Full theoretical documentation and method comparison are recorded in the artifact
  ~/.gemini/antigravity-cli/brain/64e83b30-2edb-4b3e-9633-8b852a22917e/motif_scoring_and_architecture.md.
  ──────
  ### Architecture Overview

  │ Diagram exceeds terminal width (193 > 118 cols)
  │ Displayed as code block. Widen terminal to view inline.

    graph TD
        A["FASTA Source / Stream"] --> B["dna_analyzer.io.fasta<br/>(stream_fasta / read_fasta)"]
        B --> C["dna_analyzer.models.sequence<br/>(DNASequence & FastaRecord)"]
        C --> D["dna_analyzer.algorithms.pattern_count<br/>(Overlapping & k-mer search)"]
        C --> E["dna_analyzer.algorithms.scoring<br/>(LogOddsPWMScorer / Protocol)"]
        D --> F["dna_analyzer.pipeline<br/>(Reproducibility & Provenance)"]
        E --> F
        F --> G["AnalysisRunRecord<br/>(JSON Audit Trail with SHA-256)"]

  The codebase is organized into small modules:

  • src/dna_analyzer/models/sequence.py: Immutable DNASequence (canonical {A,C,G,T} & IUPAC degeneracy validation,
  GC%, reverse complement) and FastaRecord (identifier and accession version tracking).
  • src/dna_analyzer/models/motif.py: Validated PositionFrequencyMatrix (PFM), PositionWeightMatrix (PWM), and
  BackgroundFrequencies.
  • src/dna_analyzer/models/provenance.py: Immutable AnalysisRunRecord, SoftwareEnvironment, and
  InputSequenceProvenance for audit trails.
  • src/dna_analyzer/io/fasta.py: Memory-efficient streaming (stream_fasta) and batch (read_fasta) parsers that
  preserve headers, IDs, accession versions, and compute file/sequence SHA-256 hashes.
  • src/dna_analyzer/algorithms/pattern_count.py: Overlapping pattern counting (e.g. finds both occurrences of ATAT
  in ATATAT at indices [0, 2]), strand awareness (+, -, or both), IUPAC lookahead regex, and sliding k-mer
  enumeration.
  • src/dna_analyzer/algorithms/scoring/pwm.py: Biophysical Log-Odds PWM scorer (Berg & von Hippel additive free-
  energy model) with configurable pseudocounts, background GC-tuning, and normalized [0.0, 1.0] affinity scanning.
  • src/dna_analyzer/algorithms/scoring/base.py: Formal MotifScorer protocol and catalog of alternative mathematical
  models (Information Content, Statistical Enrichment, Mismatch Penalty).
  • src/dna_analyzer/pipeline.py: Reproducible execution orchestrator that bundles sequence hashes, runtime versions,
  parameters, and results, with verify_reproducibility for tamper detection.
  ──────
  ### Motif Scoring Method: Assumptions & Mathematical Rules

  Based on your selection, the implemented scoring method is the Biophysical Log-Odds Position Weight Matrix (PWM):

  1. Biological Assumptions:
      • Additive Free Energy (Berg & von Hippel): Nucleotide positions in the transcription factor binding site
      (TFBS) contribute additively and independently to total binding affinity (ΔΔGₜₒₜₐₗ ≈ ∑ᵢ₌₁ᴸ ΔΔGᵢ).
      • Equilibrium Occupancy: Observed frequencies follow a Boltzmann distribution relative to a genomic background
      null state q = (q_A, q_C, q_G, q_T).
      • Small-Sample Regularization: Zero observations reflect sampling limitations, corrected with background-
      scaled pseudocounts (p).
2. Mathematical formulation
The equations below have been reformatted for readability.
Probability estimate at position i for base b
Log-odds weight
Raw window score
Normalized affinity score (0.0 ≤ Snorm ≤ 1.0)
  ──────
  ### Automated Test Suite (pytest)

  A test suite containing 61 tests covers:

  • Known sequences: Overlapping repeat counting (ATAT in ATATAT), homopolymers (AA in AAAA), exact analytical log-
  odds and normalized scores against manual calculations, reverse-complement hits.
  • Invalid inputs: Sequences with non-canonical characters, malformed FASTA headers, empty query patterns, invalid
  matrix dimensions, negative pseudocounts.
  • Boundary cases: Sequences shorter than motif/pattern length, single-base inputs, empty FASTA files, Windows CRLF
  line endings, ambiguous base N handling.
  • Reproducibility verification: Checksum verification and detection of mutated/tampered sequences.

  Run tests with uv:

    uv run pytest -v

  (All 61 tests passing in 0.09s).
  ──────
  ### Usage Example

    from dna_analyzer.io import read_fasta
    from dna_analyzer.models import PositionFrequencyMatrix, BackgroundFrequencies
    from dna_analyzer.algorithms import LogOddsPWMScorer, count_overlapping_patterns, StrandMode
    from dna_analyzer.pipeline import run_motif_scan_analysis, verify_reproducibility

    # 1. Load FASTA preserving identifier and metadata
    records = read_fasta("tests/test_sequences.fasta")
    record = records[0]

    # 2. Overlapping pattern search
    result = count_overlapping_patterns(record.sequence, pattern="TGGC", strand_mode=StrandMode.BOTH)
    print(f"Total overlapping matches: {result.total_count}")

    # 3. Biophysical motif scoring
    pfm = PositionFrequencyMatrix(
        name="core_promoter",
        matrix={
            "A": [8, 0, 8, 0],
            "C": [0, 0, 0, 0],
            "G": [0, 0, 0, 0],
            "T": [0, 8, 0, 8],
        }
    )
    bg = BackgroundFrequencies.from_gc_content(record.sequence.gc_content / 100.0)
    scorer = LogOddsPWMScorer(pfm, background=bg, pseudocount=1.0)

    # 4. Reproducible run with full audit trail
    audit_run = run_motif_scan_analysis(record, scorer=scorer, min_score_ratio=0.8)
    audit_run.save("audit_run.json")

    # 5. Verification by another researcher
    assert verify_reproducibility(audit_run, record) is True

  Refer to README.md and pyproject.toml for project metadata and configuration details.
Compare our one-line request with the detailed prompt. The second already told the assistant what to build, how to record the inputs, and how to test the result. Gemini still had two choices it needed us to make. An assistant can explain the options, but we need to understand them well enough to choose what serves our research question and check the result.
Start by counting an overlapping pattern in a short sequence you can check by hand. You’ll learn how to store the sequence, move a window, and test the result. Bring in a FASTA reader when you need to load a real file, and learn about scoring when an exact match no longer answers your question.
Deterministic Calculations and Reliable Results
There is one more useful concept to understand: determinism.
A deterministic calculation gives the same result when it receives the same inputs under the same defined conditions.
Suppose we want to count how many times the DNA pattern AT occurs in the sequence ATAT.
seq = "ATAT"
pat = "AT"
n = len(pat)
positions = []
for i in range(len(seq) - n + 1):
    if seq[i:i + n] == pat:
        positions.append(i)
print(len(positions))2The loop checks one starting position at a time and saves each match. Here it finds AT at positions 0 and 2. With the same sequence and rule, it will print 2 each time.
A large language model can give a different answer each time. If we ask it to write a new counting algorithm whenever we need one, we may get different implementations, assumptions, or errors.
Instead, we can develop a small function, test it, and reuse it whenever that calculation is needed.
An AI agent can then call our tested function rather than attempting to perform the calculation itself or rewriting it every time.
The agent’s decisions may still vary, and some scientific algorithms deliberately use randomness. We can manage those cases by defining the workflow, recording settings, and fixing random seeds when appropriate.
But the essential idea remains: we want reliable scientific calculations performed by software whose behavior we understand and can test.
This is also one of the central ideas behind our Genome Toolkit series. We progressively develop a Python package that can load biological data, run algorithms, validate inputs, and produce structured scientific results.
In Genome Toolkit Parts 4.6 and 4.7, we explore structured results, automated tests, and clearer error handling. These are practical skills that become increasingly valuable when our software is used by other researchers, applications, or AI agents.
Part 4: Choose a Scientific Problem and Start Exploring
Now that we have discussed the fundamentals, let’s return to the most important question: what do we actually want to investigate?
We’ll look at a few starting points. Pick one small question you can answer, use the result to ask a second question, and let those steps grow into a project you can explain and share.
1. Genome Assembly
Imagine looking at a set of short DNA reads from a study. You can find public reads in the Sequence Read Archive at NCBI. A read is one piece of sequence, not the whole chromosome. How would we tell where one piece ends and the next begins?
Sequencers read pieces of DNA, and the length of those pieces depends on how the data were collected. The whole chromosome is much longer than any one read in this example, so we use many reads to piece it back together. One common Illumina setup reads 150 bases from each end of a fragment. PacBio HiFi reads can typically span 15,000 to 25,000 bases. The reads can overlap, but their order in the file doesn’t tell us where they belong in the chromosome. Check NCBI Datasets for an existing assembly from the same sample. If one exists, we already have something to compare our work against.
Try the same overlap with two endings. The two-read Python example in Part 1 joined ATGC and TGCA. Try TGCA and TGCT as the second read in the same loop.
left = "ATGC"
for right in ("TGCA", "TGCT"):
    ok = left[1:] == right[:3]
print(ok, left + right[3:])True ATGCA
True ATGCTBoth candidates share the overlap TGC. One join ends in A and the other ends in T. What extra evidence would help you decide which one belongs in the genome?
That small problem gives us a learning plan. Learn enough Python to compare the strings, then draw a line between pieces that can join. One piece can lead to two different choices. Some short-read assemblers, such as Velvet, use de Bruijn graphs to represent connections between short patterns. An Eulerian path follows each connection once. Our little drawing helps explain the idea. Real datasets also have errors, repeats, and gaps, so a possible join needs evidence.
Once we can join reads that match perfectly, another question comes along. What if one letter is different? Line up ATGC and ATGT. They match in three places and differ in one. Counting those differences between two strings of the same length is called Hamming distance. That gives us a way to start looking for close matches.
Now we have a reason to learn about changes in DNA. Was that different letter a mistake made while reading the DNA, or a real difference between two samples? We could look at other reads covering the same place to help us decide. As we explore real differences, we’ll meet the term single nucleotide polymorphism, or SNP, pronounced “snip”. It describes a difference at one DNA letter between genomes. One small mismatch has opened up a whole new question about the organism.
We started with one question: how can we reconstruct a genome from a file full of reads? A small Python loop helps us compare strings. Hamming distance lets us count mismatches in equal-length strings. De Bruijn graphs and Eulerian paths give us ways to think about connections, and SNPs give us a reason to check whether a mismatch reflects a real difference. This is the approach we started with in Part 1. Pick a question you care about, then learn each tool when you have a reason to use it.
For a first research project, try assembling a small public dataset that has a published assembly. Use an established assembler, compare the result with the reference, and record where your reconstruction agrees or breaks down. Share the accession, commands, and results so someone else can rerun them. Once you can do that, you can look for a dataset without an assembly and ask a researcher familiar with it to review what you recovered. A well-documented result, including any unresolved gaps, can be a useful contribution.
2. Finding Patterns in DNA
Scientists often examine DNA sequences to identify patterns that could provide clues about biological processes.
In the flower example in Part 1, we found the most frequent six-letter pattern and counted four copies. The next step is to record where each copy appears. We could try that with a publicly available genome.
For example, we might examine all patterns consisting of four DNA letters, identify the most frequent ones, and investigate where those patterns occur.
An interesting pattern is not automatically evidence of biological function. We would need additional information and comparisons to understand its possible significance.
However, this is an excellent way to learn about DNA, algorithms, statistics, biological databases, and scientific interpretation.
Try it with one pattern. Pick a short DNA pattern and ask where it appears in two related flower genomes. Start by counting it with a small Python function and testing the function on a sequence you can check by hand. Then compare occurrences per million bases so the bigger genome doesn’t get an automatic head start. If the pattern still stands out, ask what evidence would explain the difference.
What if we look in another flower and find GCCGAA where our first flower had GCTGAA? Our exact search treats them as different patterns. Could they still help make the same protein?
That question brings us to codons. When a cell makes a protein, it reads an RNA copy of the gene in groups of three letters. Each group tells it which small building block, called an amino acid, to add, or when to stop. In the DNA instructions, GCT and GCC can both specify the amino acid alanine. So a change in the DNA can leave the protein’s building blocks the same.
Let’s compare the two flower examples and try two other possible first triplets. Only the last letter of the first triplet changes. Each pair still gives alanine (A) followed by glutamate (E). We can check this with Python.
amino = {
    "GCT": "A", "GCC": "A",
    "GCA": "A", "GCG": "A",
    "GAA": "E",
}

for first in ("GCT", "GCC",
              "GCA", "GCG"):
    pair = amino[first] + amino["GAA"]
print(first, "GAA", pair)GCT GAA AE
GCC GAA AE
GCA GAA AE
GCG GAA AEFor a small first project, try DNA Toolkit Part 4. Work with a short DNA sequence, check its letters, and translate it into an amino acid sequence you can check by hand.
Two flowers can have different DNA spellings and still code for the same amino acids at some positions. To check whether a longer stretch codes for the same protein sequence, work out where the coding sequence starts and read the RNA copy in groups of three. You can then compare the amino acid sequences. This predicts a sequence of building blocks. It does not assemble a physical protein or tell you how it folds.
See how the questions grow? We started by asking which six letters appear most often. That led us to a database, then to genes, codons, and proteins. You can follow that path a little at a time. Each answer gives you something to try and a new question to take with you.
This direction also connects naturally to our Genome Toolkit and Ori Finder educational work, where we study DNA sequences and develop computational tools for examining them.
3. Understanding Gene Expression
Not every gene is equally active in every cell or condition.
Researchers use gene-expression data to investigate how biological activity changes between different samples.
For a first project, we could find a small published dataset and create charts comparing measurements between two conditions.
We would need to understand what the measurements represent, how the samples were collected, and why technical differences between samples matter.
Think back to the flower we noticed after dark. Searching a public sequence can help us find a candidate gene. To ask whether it is more active at night, we need a different kind of data: measurements from day and night. Start with one gene in a published dataset and plot its measured activity in the day and night samples side by side. Once you can explain that plot, compare a few genes across the same samples. You might find one that is more active at night and another that is more active during the day. Check whether those patterns repeat across flowers before drawing conclusions. A small script that finds the same DNA pattern in several published flower genomes would make a useful separate project. Share the data sources, the code, and what the comparison can tell us.
4. Studying Proteins
Proteins perform a remarkable range of tasks in living organisms, and their structures are closely connected to their functions.
We could begin by selecting a well-studied protein, examining its published three-dimensional structure, and learning how researchers connect structural features to biological activity.
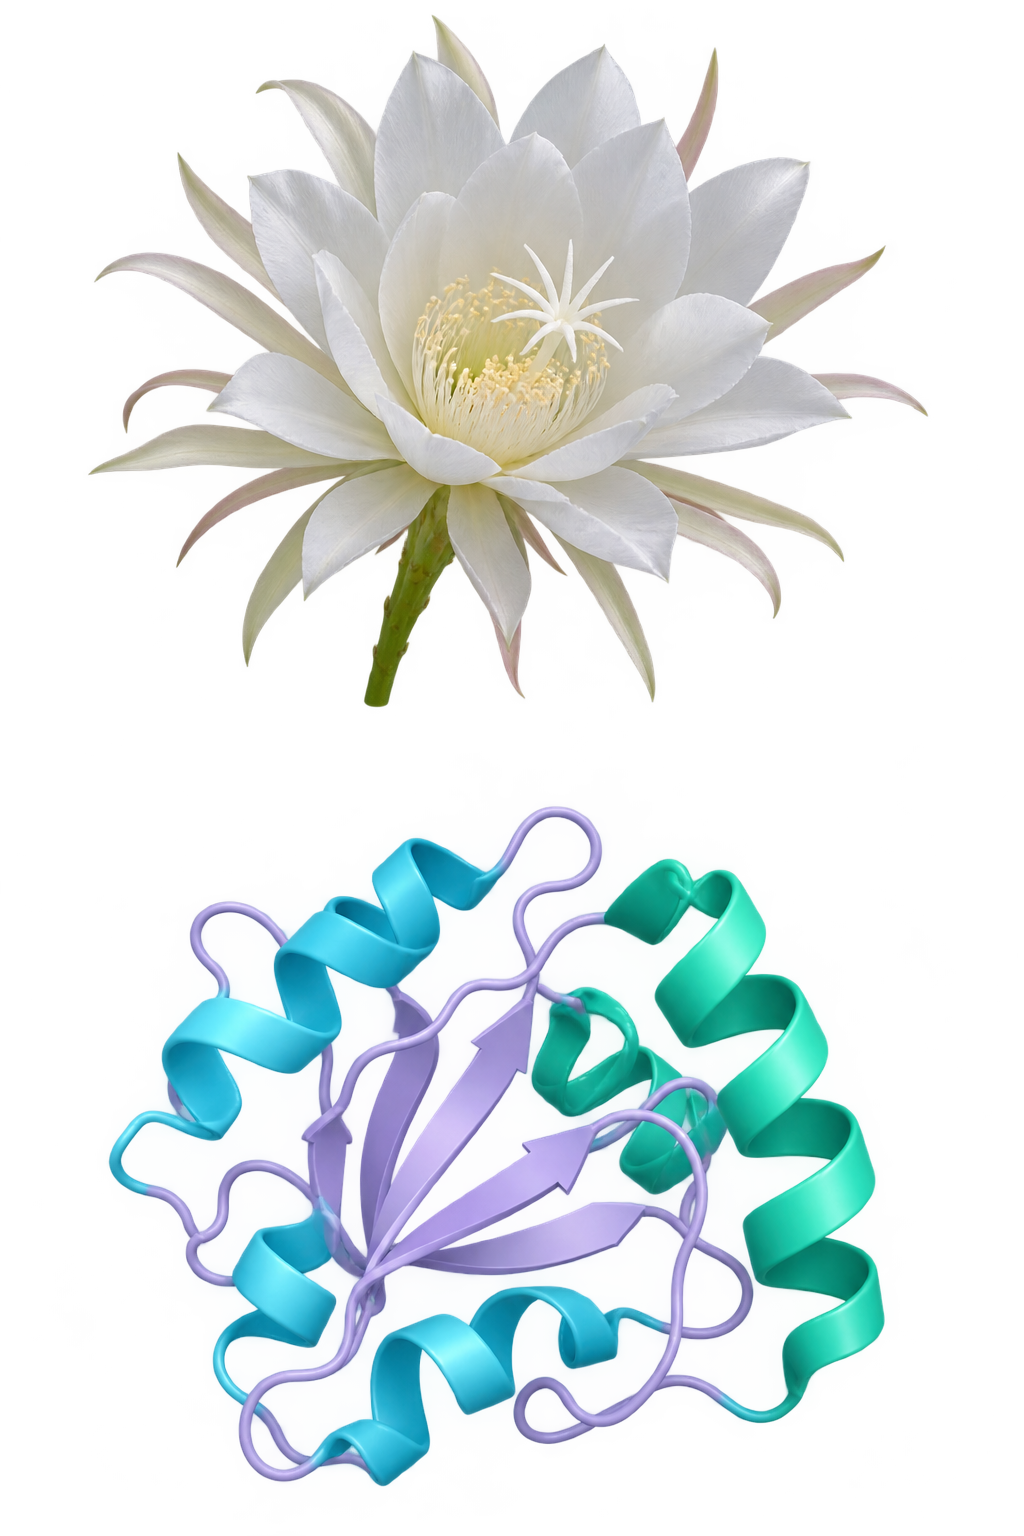
Look for a published structure
Pick a protein whose shape has already been studied. Imagine turning the structure around on screen. What can you see from another angle?
Ask one question about its shape
Which part might help it do its job? Could a change in one building block affect that part? Read what researchers have found and see whether it helps answer your question.
5. Reproducing Published Research
Published papers are useful once we have a question and enough background to follow part of the answer. Starting with a full paper and trying to reproduce it can be a frustrating first assignment. Papers are usually written for readers who already know the vocabulary, the biology, and much of the maths behind the methods. An AI assistant can explain a paragraph or a term, but working through dozens of unfamiliar ideas at once still takes time.
Try a smaller question first. Write a program that finds a pattern in a short string and check the matches by hand. If assembly interests us, we can use a few short example reads, draw which ones overlap, and write a small Python program that follows those connections. That helps us see why sequencing produces fragments, how overlaps help us connect them, and why a simple example is easier than assembling a real genome. We can use AI to explain or draft a step and check that step ourselves.
When those ideas make sense, a published paper becomes a source we can turn to for a particular question. We might select a study with accessible data and enough information to repeat one calculation or recreate one figure. That is a worthwhile project on its own.
Our goal would be to understand what the researchers measured, identify the software and methods they used, reproduce one small part of their analysis, and compare our results with those reported in the paper.
This can be particularly useful for someone with a background in laboratory biology who wants to improve their computational skills.
It also teaches an essential scientific habit: checking how a result was obtained instead of accepting it simply because it appears in a table or chart.
Which Direction Should You Choose?
Pick something that makes you curious enough to keep asking questions.
It is completely fine if your first project is small, if you reproduce work that already exists, or if you discover that you are more interested in another area halfway through.
The important part is to have a question that gives your learning a purpose.
If you’re unsure what to learn first, start with a short brainstorming session. Tell an AI assistant what you’re curious about, what you already know, and how much time you can spend. Ask for two or three questions you could investigate with public data. Pick the one you’d still want to answer if the first attempt failed. Then ask what you need to learn to take the very first step. The assembly example might send you straight to Python strings, while a gene expression question might start with reading a table. The prompt in Part 5 can help you find that starting point.
Small Projects We’ll Explore in More Detail
Bioinformatics covers more questions, tools, and ways to contribute than we can teach in one guide. Here we’re giving you an overview and a starting path. We’re planning shorter articles and videos that each take one research idea from a question to a result someone else can check. We’ll show how to choose a goal you can reach, find suitable data, decide which tools to learn, and share what you found. We’ll use freely available tools and public data wherever we can.
For example, you might start with a small Python project that summarizes the lengths of public genome assemblies from NCBI Datasets. Once it works on a few files, you could use Nextflow to run the same steps on a larger collection and make the analysis easier for someone else to repeat. If you later have access to an Oxford Nanopore sequencer, working with reads you collect yourself opens up another set of questions. You can also start learning to assess long-read quality with public data.
Turn one question into a project
This workflow is one possible starting point. Pick a question you care about and make it small enough to test. As you work toward an answer, you’ll learn which tools you need. Save your code, results, and a short note on what you learned so you have something to share in your portfolio.
Part 5: A Step-by-Step Plan with Free Tools and Resources
So here we are, at the practical part of the guide.
We want a learning path that makes sense, uses free resources, and allows us to apply what we learn rather than simply collecting completed courses.
You do not need to follow every resource in this section. If you already know Python, you can skip much of the programming introduction. If you have a strong biology background, focus on the computational skills that will help you investigate your own questions.
For complete beginners interested in computational bioinformatics, I recommend the following route.
Step 1: Learn Python With Programming for Lovers
Our main recommendation is Programming for Lovers, a free programming course developed by Phillip Compeau, who also teaches the well-known Bioinformatics Specialization with Pavel Pevzner.
What makes this course particularly interesting is its approach.
Instead of teaching programming concepts entirely in isolation, it connects them to scientific and mathematical problems.
One chapter explores hidden patterns in bacterial genomes, while other chapters investigate subjects such as simulation, cellular automata, and evolutionary trees.
The course provides free reading materials, Python code-alongs, and exercises that let us practise what we have learned. Its main online curriculum does not require a paid subscription or account.
I would start with Chapter 0, continue into Chapter 1 on bacterial DNA analysis, and then explore the other chapters as time allows.
The goal is not simply to watch someone write code. We should pause, try the examples ourselves, understand the algorithms, and experiment with small changes.
If you prefer learning from video tutorials, I also recommend Corey Schafer’s Python tutorial playlist.
Corey explains Python clearly and covers the fundamentals we discussed earlier. His videos make an excellent supporting resource whenever we encounter a Python concept that needs more explanation.
You don’t need to complete two entire programming courses before moving on. Use whichever explanations help you understand the material, and spend plenty of time practising.
Step 2: Solve Your First Bioinformatics Problems With Rosalind
Once you have some basic Python experience, visit Rosalind.
Rosalind is a platform dedicated to learning bioinformatics through programming problems. Many challenges introduce a biological concept, explain the computational task, and ask you to solve it using code.
It was developed by educators and researchers connected to the same community behind the Bioinformatics Specialization.
In Rosalind, open Problems, choose List View, and select Bioinformatics Stronghold. The five exercises below are a suggested route through that list.
- Counting DNA Nucleotides — Practise counting the four DNA letters.
- Transcribing DNA into RNA — Learn how DNA and RNA sequences are related.
- Complementing a Strand of DNA — Learn about complementary DNA bases and sequence orientation.
- Computing GC Content — Calculate the proportion of G and C bases in DNA.
- Finding a Motif in DNA — Search for the positions of a short sequence pattern.
These exercises give us a natural progression from basic programming to useful sequence-analysis algorithms.
Try these five yourself. For each one, explain what goes in, what comes out, and why each step of your solution works. If you get stuck, ask the assistant to explain a concept or help you find an error.
This approach helps us build the skills we will need when the problems become more complicated.
Step 3: Use AI as Your Personal Learning Assistant
We now have an additional resource that wasn’t available in anything like its current form when the original guide was published: capable AI assistants.
If you cannot afford a paid subscription, that should not stop you from experimenting with AI-assisted learning.
I recommend starting with Google Gemini. On a computer, sign in, open the tools menu beside the message box, and select Guided Learning. Give it a concept or a small problem you want to work through. Google’s Guided Learning instructions
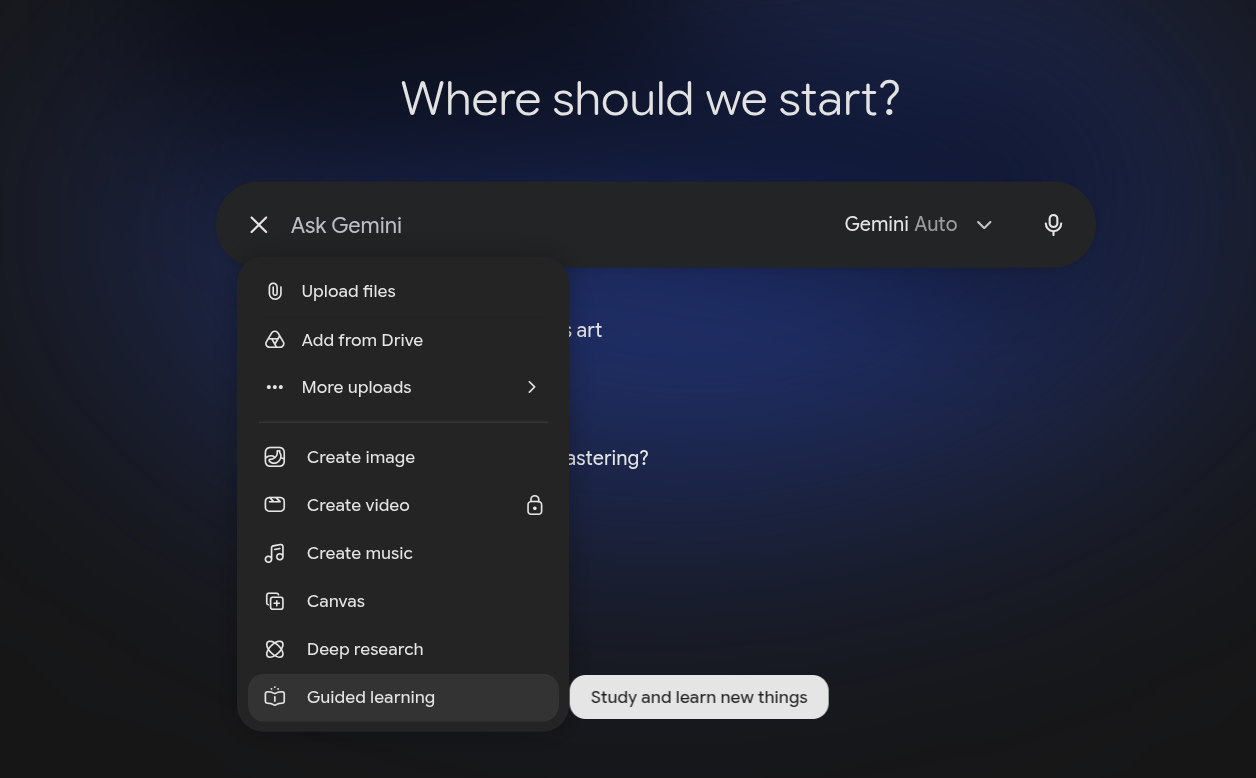
A free Google account is usually enough for beginner and intermediate learning sessions and small Python projects you run on your computer. We can use the free models to work through an unfamiliar concept, understand an error, or review a short piece of code. Paid plans are worth considering when a large codebase or a complex research task regularly needs more context or more usage than the free plan offers.
Less than a year ago, you generally needed a paid plan for the kind of help you can now get from a free Gemini account. Free models have come a long way, and the free allowance gives us plenty of room to work through a lesson or get a small Python project off the ground.
ChatGPT is another option, with a Study Mode intended for guided learning.
The most important part is how we use these tools.
A Prompt to Find Your Own Research Direction
Here is an example you can copy into your preferred AI assistant:
I want to start learning bioinformatics, but I am not completely sure which area interests me most.
Act as a patient scientific mentor. Ask me questions one at a time about my background, interests, and goals.
Help me choose one realistic biological question that I could investigate using free learning resources, publicly available data, and beginner-friendly tools.
Once we have chosen a direction, explain which biology, programming, mathematics, or statistics concepts I need to understand.
Create a practical learning plan with small exercises and a first project that I can complete and publish on GitHub.
Explain unfamiliar terms in simple language, recommend original scientific or educational sources where possible, and help me check whether the information and results are correct.
Please guide me through the learning process rather than immediately doing all the work for me.
You can adapt that prompt to your particular interests.
If you are already a biologist, tell the assistant which experiments or data types you work with. If you are a software developer, describe your programming experience and ask which biological fundamentals are relevant to your chosen project.
For a small learning exercise, ask the assistant for a worked example and run it on an input you can check by hand. That gives you a way to learn and check the result at the same time. For a new research claim or a more complex analysis, ask for the original sources, check how the data was collected, and use independent tests before relying on the result.
Step 4: Build Your First Small Bioinformatics Project
Now it’s time to apply what we’ve learned.
Let’s imagine that we want to create a small tool that examines DNA sequences.
We could call it Genome Pattern Explorer.
Our first version would perform a few simple operations:
- Read a DNA sequence from a FASTA file.
- Check that the input follows the format our program expects.
- Count the occurrences of A, C, G, and T.
- Calculate GC content.
- Search for short DNA patterns.
- Display the results in a readable format.
FASTA files can be downloaded from public biological databases such as the NCBI Datasets service.
We should keep a record of the exact sequence we downloaded, including its identifier and version. This becomes important when we compare our results with those of other researchers.
Start with one operation you can check by hand. Set all four counts to zero, then read AACG one letter at a time.
sequence = "AACG"
counts = dict.fromkeys("ACGT", 0)
for base in sequence:
    counts[base] += 1
print(counts){'A': 2, 'C': 1, 'G': 1, 'T': 0}That prints two As, one C, one G, and zero Ts. Once the counter gives the expected result on this example, try it on a real public DNA sequence. The same code that counts four letters can help you explore a sequence too long to count by hand.
Then ask a few questions.
What happens if the sequence contains lowercase letters? What if it includes an unknown nucleotide symbol? What if the pattern does not exist? What if it occurs more than once, including at overlapping positions?
These are great opportunities to learn about testing and software behavior.
Finally, create a GitHub repository containing your code, a description of the project, instructions for running it, the source of your biological data, and a few examples of verified results.
It doesn’t need to be a large project. A small program that you understand and can explain is more valuable as a learning exercise than an impressive-looking application that you don’t know how to maintain or test.
Step 5: Make Your Project More Reusable
Once your first program works, we can start improving it.
Perhaps we want to separate the FASTA loader from the sequence-analysis algorithms. Maybe we want to add automated tests, improve error messages, or record additional information about our results.
This is where the practices from Part 3, Master the Fundamentals of Programming and Scientific Research become useful. Keep the FASTA loader separate from the analysis, test the code on a sequence with a known answer, and record the input sequence version and settings so someone else can repeat the analysis.
We can learn how to create a proper Python package, use uv to manage its dependencies, add tests with pytest, and organize the code so other programs can import our functions.
Later, we might expose those functions through an interface that an AI agent can use.
This does not mean abandoning ordinary scripts or writing unnecessary software infrastructure. Simple scripts are still extremely useful for learning and exploratory work.
The goal is to understand how a small experiment can gradually become a reusable and trustworthy scientific tool.
Our Genome Toolkit series follows a similar approach, starting with simple DNA algorithms and gradually developing a more complete scientific Python package.
Part 6: Additional Resources and Where to Go Next
At this point, we have a practical starting path. We understand why programming and biology fundamentals matter, we have free resources for learning them, and we have several ideas for our first scientific projects.
As we develop our skills, we will probably encounter subjects that deserve more serious study.
Depending on the direction we choose, these might include statistics, algorithms, graph theory, molecular biology, genetics, experimental design, or advanced software engineering.
We do not need to learn all of them immediately. We can return to a subject when a research question gives us a reason to understand it.
The Original Bioinformatics Courses Are Still Worth Considering
In the original version of this guide, I recommended the introductory bioinformatics course from Pavel Pevzner and Phillip Compeau, followed by their complete seven-course specialization.
When we first published this guide in 2020, we recommended the introductory course because you could take it for free. Coursera replaced free auditing with course previews. A preview lets you try the material, and full access generally requires payment or financial aid. Both courses remain among our favorite ways to get started. If the introductory course fits your budget, we think it is worth paying for. You can also make a strong start with the free and open resources in Part 5.
The two recommendations are:
Biology Meets Programming: Bioinformatics for Beginners
This introductory course connects Python programming with biological problems and offers a gentle introduction to the larger specialization.
This seven-course program explores computational biology, genome analysis, algorithms, and other important subjects in greater depth.
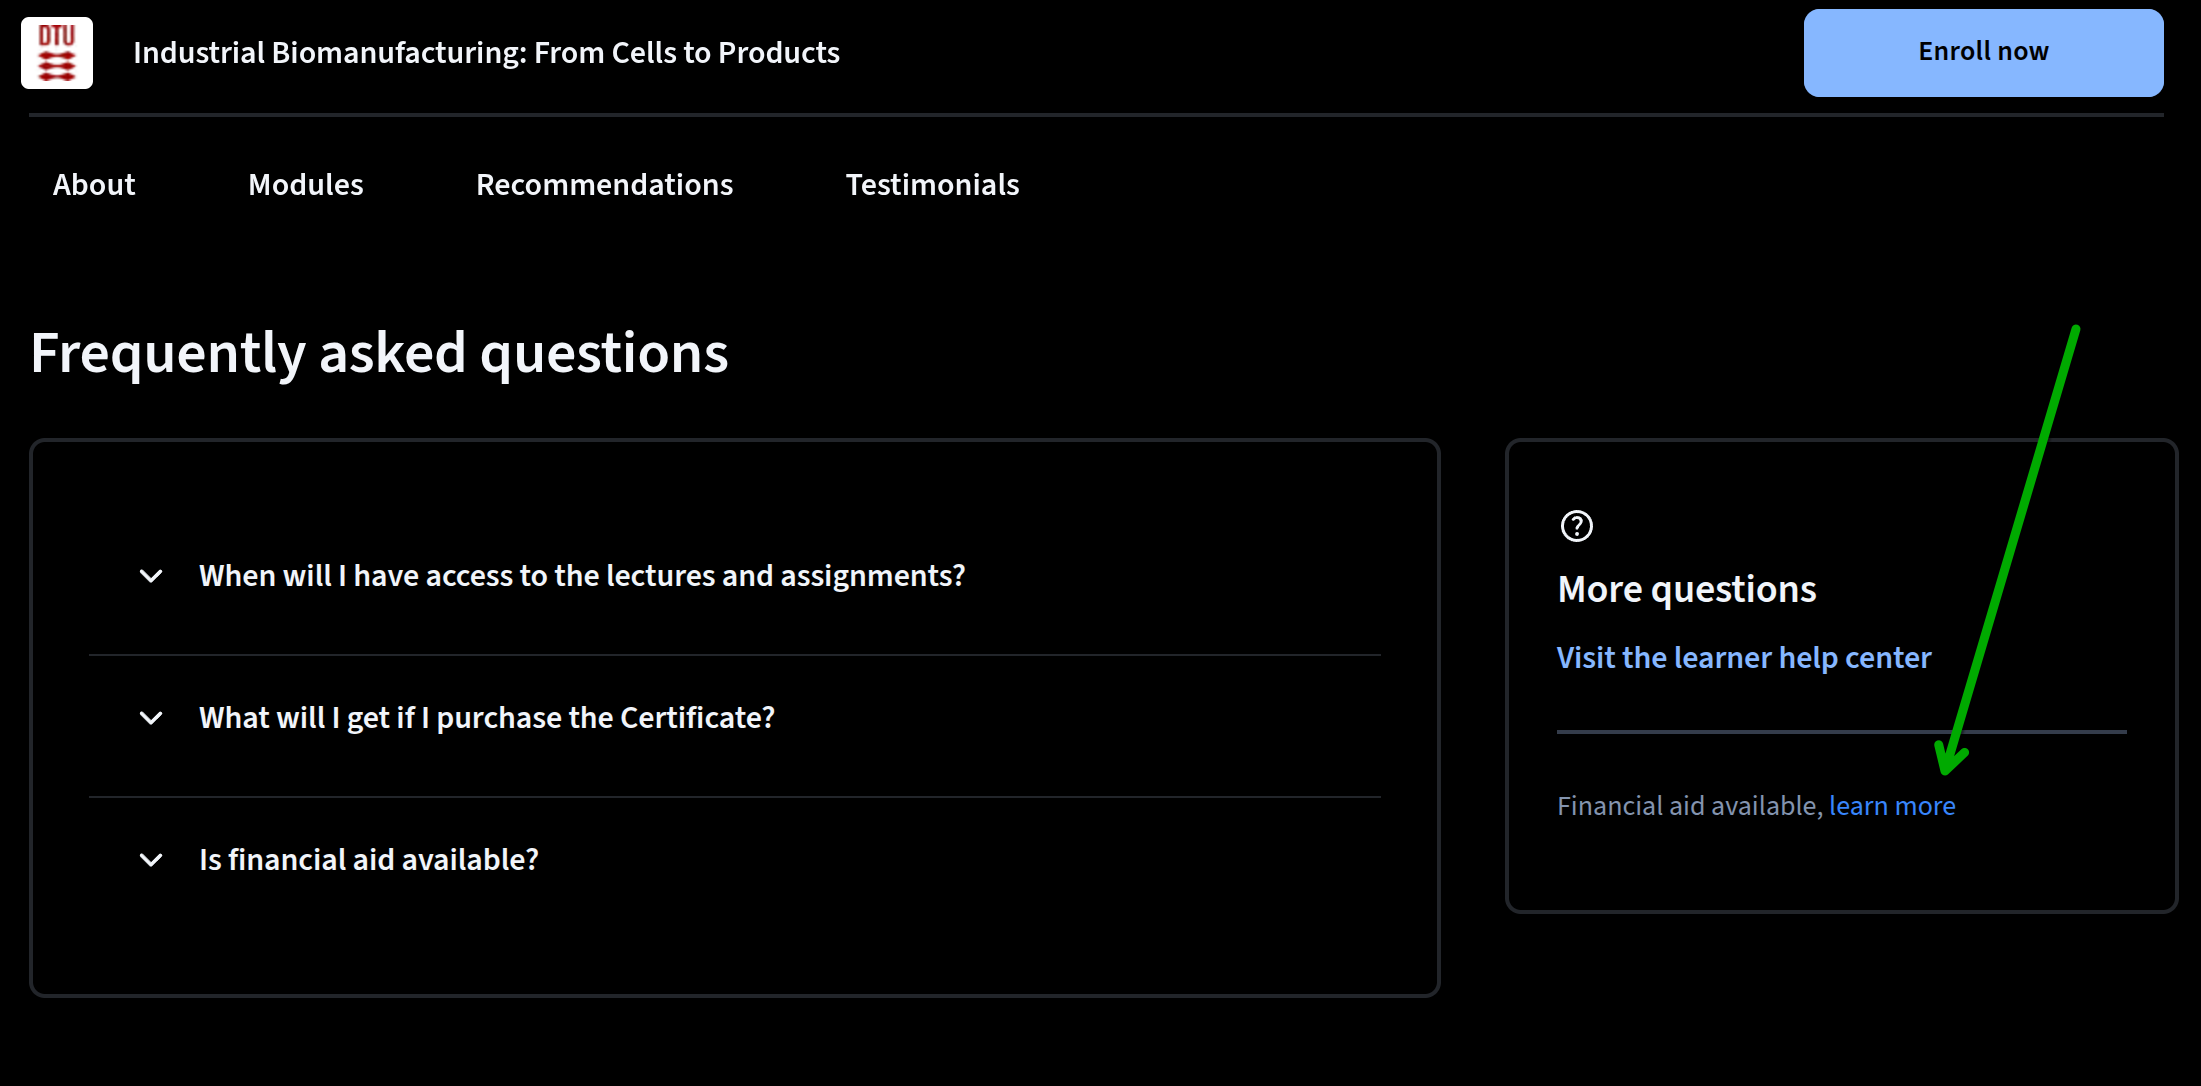
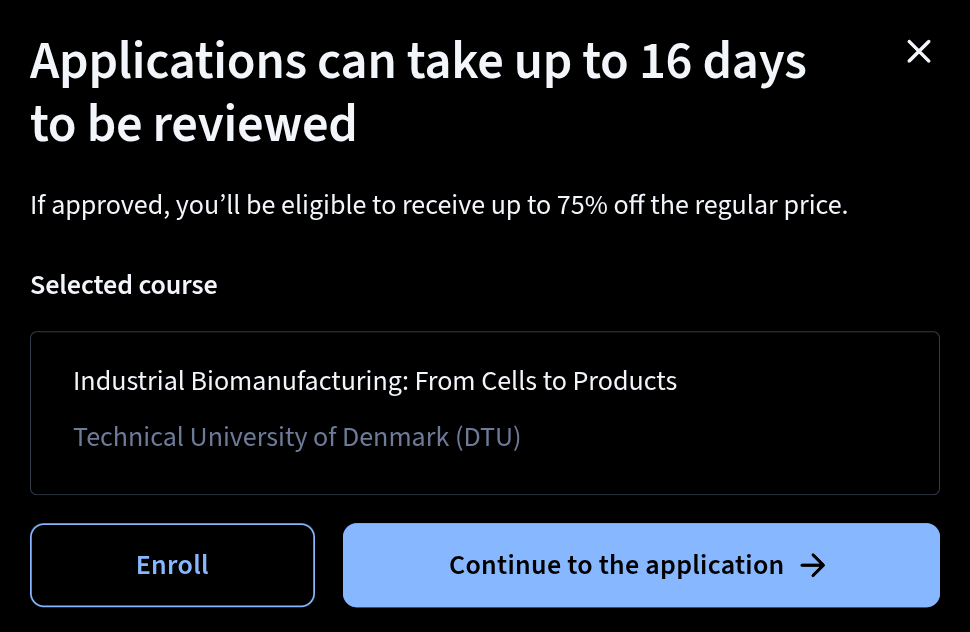
If course fees are a barrier, check each course page separately for financial aid. You may need a separate application for each eligible course. For example, open Industrial Biomanufacturing: From Cells to Products, scroll to Frequently asked questions, and look under More questions. In the screenshot below, the link is in the lower right of the FAQ. Select Learn more beside Financial aid available. The dialog explains the aid offered for that course and links to the application. Select either screenshot to enlarge it.
Learning Without a University Degree
There is another important change worth discussing.
Access to high-quality educational material has improved considerably. We can now study programming, biology, mathematics, statistics, and advanced computational methods using freely available courses, scientific publications, public datasets, and AI assistance.
That makes it possible to develop substantial practical skills outside a traditional degree program.
Keep this education free
We created REBELSCIENCE to share free, high-quality education in bioinformatics and open-source software. If it helps you, support the project or share your thoughts in the comments. That helps us make more free guides and lessons.
We can write software, reproduce published computational experiments, contribute to open-source projects, and build a portfolio that shows what we know and what we can do.
Formal education is still important, particularly for many laboratory positions, regulated work, and academic research careers. A portfolio or a collection of online courses does not automatically replace a bachelor’s degree, master’s degree, or PhD.
But we don’t necessarily need to wait for a university qualification before beginning to learn, experiment, and contribute to suitable open-source projects.
What matters is that we approach the subject seriously, understand the methods we use, and are honest about what our projects can and cannot demonstrate.
What Will Employers Look For in the Age of AI?
Nobody can predict exactly how the job market will change as AI becomes more capable.
However, being able to ask an AI assistant to produce code is only one part of developing useful scientific software.
Consider two people applying for a role involving biological data analysis.
One can ask an AI agent to generate an analysis pipeline and obtain a result. The other can do that too, but also understands the biological data, can explain the algorithms, identify incorrect assumptions, test the software, and reproduce the results.
For a position where scientific reliability matters, the second person can demonstrate a much broader set of useful skills.
It is not just about how quickly we can generate software. It is about whether we understand what we have created and can trust it for its intended purpose.
This becomes particularly important when scientific software contributes to medical research, laboratory decisions, or other work where incorrect results may have serious consequences.
A strong portfolio can help show those skills.
Instead of uploading a collection of unrelated code examples, consider developing a few projects that answer meaningful questions. Explain the problem, the methods you selected, the data you used, the results you obtained, and the limitations you encountered.
Show how you tested your code and how another person could reproduce your work.
These are valuable habits whether you develop the software manually, with AI assistance, or through a combination of both.
Join a Community and Share Your Ideas
Learning becomes much easier when we can discuss problems with people who share our interests.
If you’re unsure which direction to take, have an interesting biological question, or want to discuss a potential project, feel free to join our REBELSCIENCE community.
You might have discovered a scientific paper and want to understand how to reproduce its results. Perhaps you’re a programmer interested in contributing to computational biology, or a biology student trying to choose your first Python project.
We can exchange ideas, discuss learning resources, and help each other find practical ways forward. If you have a project idea, a tool you’d like to learn, or a research question you’d like to see us break down, leave a comment under this article or its video version, or share it in the community. Tell us what you’d like to do and where you’d want help getting started. Your ideas will help us choose what to cover in the shorter articles and videos.
You’ll find Matrix and Telegram through REBELSCIENCE.
There are also excellent broader scientific communities, such as Biostars, where people discuss bioinformatics questions and methods.
When asking for help, try to explain what you’re investigating, what you’ve already attempted, and where you’re having difficulty. These details make it much easier for other people to understand the problem and offer useful guidance.
Summary
Bioinformatics is an enormous and rapidly changing field. There is no single learning path that will suit everybody, and we certainly don’t need to understand every part of biology or computer science before we can begin.
The approach I recommend is straightforward.
Start with a question that interests you. Learn the fundamentals you need to investigate it. Use AI to help you learn and automate appropriate tasks, and apply your new knowledge by building something real.
Modern AI assistants can make programming and research considerably more accessible. But the ability to understand scientific problems, choose suitable methods, ask precise questions, and check results remains essential.
Python is an excellent starting language for computational work. Programming for Lovers, Corey Schafer’s tutorials, and Rosalind provide a practical combination of explanations and exercises, all accessible without following a paid learning path.
From there, we can develop a small project using public biological data, introduce testing and reproducibility, and gradually learn how to build more capable scientific software.
A well-understood project is a good foundation for the next one.
What’s Next?
If you’re completely new to bioinformatics, begin by exploring the research directions in Part 4. Choose one that sounds interesting and use the AI learning prompt to help develop a simple plan.
Then start learning Python, solve a few Rosalind challenges, and create your first small project.
If you already have programming experience, you can begin with a biological question and learn the relevant science alongside your implementation. If your background is in biology, use your existing scientific knowledge to guide the programming skills you develop.
As your experience grows, our Genome Toolkit series offers a way to explore scientific software development more deeply.
We will continue reviewing this guide as useful new resources, research methods, and AI tools become available.
Most importantly, remember that you don’t need to have your entire future planned before getting started. An interesting question and a willingness to investigate it are enough to begin.
Until next time, rebelCoder, signing out.
Video version of this article
Part 1 · Getting started in bioinformatics
Part 2 · From Python to your first project
Loading the conversation…